DBpedia Dataset: A Complete Guide to Structured Knowledge and Semantic Web Data
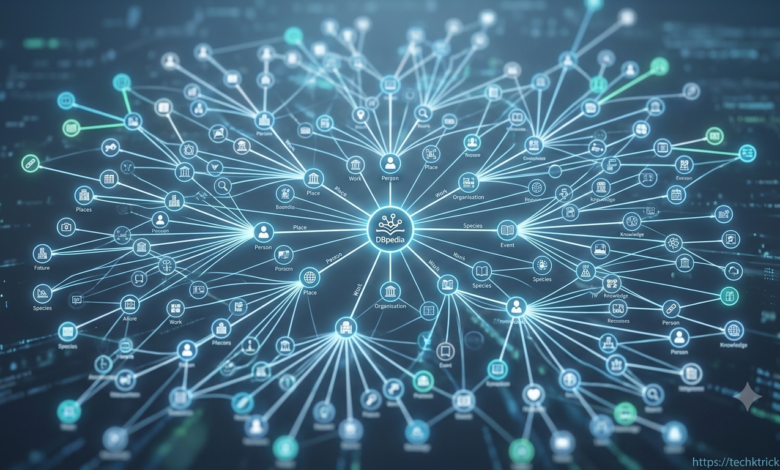
The DBpedia dataset is an important resource in the fields of artificial intelligence, knowledge graphs, semantic web technology, and data science. It transforms information from Wikipedia into structured, machine-readable data that computers can use to understand relationships between people, places, organizations, events, and other real-world concepts.
For researchers, developers, students, and businesses, DBpedia provides a practical way to work with interconnected information instead of relying entirely on unstructured text. It supports knowledge discovery, intelligent search, natural language processing, and applications that require information from multiple sources.
This guide explains what the DBpedia dataset is, how it works, its main features, common applications, benefits, limitations, and how beginners can start using it.
What Is the DBpedia Dataset?
The DBpedia dataset is a large collection of structured information extracted primarily from Wikipedia. It organizes information into machine-readable statements so that software applications can identify entities and understand how they relate to one another.
For example, a Wikipedia article about a country might contain information about its capital, official language, population, location, and neighboring countries. DBpedia represents many of these facts as structured relationships that computers can query and process.
DBpedia is closely associated with the Semantic Web, an approach to organizing information so that machines can interpret the meaning of data and its connections. Instead of treating every page as an isolated document, DBpedia helps represent knowledge as a network of linked entities.
The project began in 2007 and became an influential example of how collaboratively created online information can be converted into reusable structured data. Its resources have supported academic research, knowledge graph development, and semantic technologies.
It is important to understand that DBpedia is not Wikipedia itself. Wikipedia is primarily an encyclopedia intended for human readers, while DBpedia provides structured representations of information that can be used by computers and data-driven applications.
How Does the DBpedia Dataset Work?
The DBpedia dataset is created through a process that extracts information from Wikipedia and maps it into structured formats. The extracted information can then be published as linked data, making it easier for applications to access and connect facts.
The process generally involves several stages.
First, information is collected from Wikipedia pages, including structured elements such as infoboxes, categories, links, and other available page information. These elements provide clues about the entities described and their properties.
Second, the information is transformed into a standardized representation. Different Wikipedia articles may describe similar concepts using different wording or layouts, so extraction and mapping processes help represent comparable information consistently.
Third, facts are organized into relationships. For example, a statement may identify a person as the author of a book or a city as the capital of a country. These relationships allow computers to retrieve specific information without reading an entire article.
Finally, the resulting data can be published in formats such as RDF and accessed through compatible tools and services.
A simplified example might represent the relationship between Paris and France as follows:
- Subject: Paris
- Predicate: Country
- Object: France
This is an illustrative knowledge statement rather than a guarantee that every entity or property appears in precisely that form in a particular DBpedia release.
The important principle is that the dataset expresses information as connected facts, making it useful for automated analysis and intelligent information retrieval.
Key Features of the DBpedia Dataset
The DBpedia dataset offers several features that make it valuable for researchers and developers working with structured knowledge.
Structured Data Through RDF
One of its most important features is its use of the Resource Description Framework (RDF). RDF represents facts as subject-predicate-object triples, creating a consistent way to describe relationships between entities.
For instance, a knowledge graph could represent a book, its author, and its publication date as separate but connected statements. Applications can use these statements to find related information and perform more complex searches.
A Multidomain Knowledge Base
DBpedia includes information about many different subjects, including people, geographical locations, businesses, films, books, music, scientific concepts, and organizations. This broad coverage makes it useful for projects that require connections across different fields.
Multilingual Information
The project supports data associated with multiple language editions of Wikipedia. This can help developers create applications that connect information across languages, although coverage and available properties may differ between language versions.
Connections to Other Knowledge Bases
DBpedia uses links to connect entities with related resources across the Linked Data ecosystem. These links can help applications combine information from multiple datasets, provided the relevant external resources are accessible and compatible.
Machine-Readable Information
Unlike ordinary encyclopedia prose, structured DBpedia records can be processed programmatically. Developers can retrieve specific facts, filter entities, and connect records without manually reading every source page.
Together, these features make DBpedia a useful resource for applications that depend on connected, reusable information.
What Information Does the DBpedia Dataset Contain?
The DBpedia dataset covers a wide range of entity types and relationships. Its exact contents depend on the release, language, and specific dataset files being used.
Common information categories include:
- People: Names, occupations, birthplaces, and other available biographical properties.
- Places: Cities, countries, geographical coordinates, and administrative relationships.
- Organizations: Companies, educational institutions, and other organizations.
- Creative works: Books, films, albums, television programs, and video games.
- Science and nature: Scientific concepts, species, and other categorized entities.
- Categories and types: Classifications that help software group related resources.
- External links: Connections to Wikipedia pages and other structured knowledge resources.
A record about a musician, for example, might contain information about their birthplace, musical genre, associated albums, and career relationships. Another record might describe a city and link it to its country, geographical location, and population information when available.
However, not every record contains all these properties. Some entities have extensive structured information, while others have only a name, description, category, or a small number of relationships.
For this reason, users should inspect the relevant dataset and verify which fields are populated before designing an application around them.
5. How to Access and Download the DBpedia Dataset
There are several ways to access DBpedia, depending on whether you want to explore a few facts, build an application, or analyze a large volume of data.

Official DBpedia website
Visit the DBpedia website to understand the project, explore its resources, and find documentation for available datasets and services.

SPARQL endpoint
Use the official SPARQL documentation to query supported DBpedia data online. This is convenient when you need selected records rather than a complete download.

DBpedia Association

DBpedia Databus
Visit the Latest Core collection to find downloadable dataset artifacts. Select the files and languages that match your project instead of automatically downloading everything.
Which Access Method Should You Choose?
If you are a beginner, start by exploring the online query service. It lets you test ideas without setting up a local database.
If you are developing a research pipeline or machine learning project, downloadable files may be more appropriate because you can process the data locally and repeat your analysis.
For large applications, consider maintaining a local copy of the specific data you need. This can improve control over query performance and reduce reliance on a shared public endpoint.
Keep in mind that different releases may contain different records, properties, and links. Record the dataset version and download date whenever reproducibility matters.
Understanding SPARQL Queries in DBpedia
SPARQL is a query language designed for RDF data. It allows users to retrieve information by describing patterns of relationships rather than relying only on keyword searches.
For example, suppose you want to find resources that have a label containing the word “Paris.” A simple query could look like this:
PREFIX rdfs: <http://www.w3.org/2000/01/rdf-schema#>

SELECT ?resource ?label
WHERE {
  ?resource rdfs:label ?label .
  FILTER(CONTAINS(LCASE(STR(?label)), "paris"))
}
LIMIT 10
This query searches labels in the data available to the selected endpoint and returns up to ten matching resources. It does not guarantee that all results will be cities, because labels may refer to different entities or concepts.
You can also query for entities with specific types or relationships. For example, a researcher might retrieve resources classified as cities and inspect their associated country properties.
To use SPARQL effectively, it helps to understand RDF triples, namespaces, properties, and the ontology used by the dataset. You should also check whether a property exists in the release you are querying.
The public DBpedia endpoint has query limits and may not contain every dataset published by the project. Large or complex queries can time out or return incomplete results, so it is important to review the endpoint’s usage guidance.
Practical Applications of the DBpedia Dataset
The DBpedia dataset can support many projects involving information retrieval, data integration, and knowledge representation.
Artificial Intelligence and Machine Learning
AI systems often need structured background knowledge to identify entities and understand relationships. DBpedia can provide information that supports entity linking, knowledge graph construction, and selected machine learning workflows.
For example, a research team building a system to categorize articles might use DBpedia to associate names mentioned in text with known people, organizations, or locations.
However, DBpedia alone does not provide a complete solution for modern AI. Developers may need additional datasets, trained models, and validation procedures.
Semantic Search Engines
Traditional keyword searches primarily match words. Semantic search aims to understand what those words refer to and how concepts are connected.
DBpedia can help a search application connect a person with their occupation, an organization with its location, or a creative work with its creator. These relationships can improve the relevance of search results when implemented correctly.
Academic Research
Researchers use structured knowledge resources to investigate entity relationships, compare knowledge graphs, test semantic technologies, and study linked data.
Because DBpedia covers many subject areas, it can be particularly useful for experiments that require a shared data source across multiple domains.
Data Integration
Businesses and research organizations often store information in separate systems. DBpedia can provide reference entities and external links that help connect internal records to publicly available structured knowledge.
For instance, a media company might use entity relationships to connect its internal records about films, directors, actors, and production companies.
Such integration requires careful entity matching, because different records can refer to the same name or contain inconsistent information.
Chatbots and Question-Answering Systems
A chatbot can use a knowledge graph to retrieve structured facts before generating an answer. DBpedia can support this process when the required facts are available and sufficiently reliable.
For example, a system could query relationships between a city and its country instead of trying to infer the relationship from unrelated text.
For questions involving recent events, current population figures, or frequently changing information, additional up-to-date sources may be necessary.
Benefits and Limitations of the DBpedia Dataset
Understanding both the advantages and limitations of DBpedia helps users decide whether it is suitable for their projects.
| Benefits | Limitations |
|---|---|
| Provides structured, machine-readable information | Coverage varies between entities and properties |
| Covers many different subject areas | Some information may be outdated or incomplete |
| Supports RDF and SPARQL technologies | Requires familiarity with semantic data concepts |
| Connects entities through linked data | External links may change or become unavailable |
| Supports research and data integration | Public query services have usage restrictions |
| Offers multilingual resources | Language coverage and data quality can vary |
One major advantage is that DBpedia makes information from a widely used encyclopedia available in a format that software can process. This reduces the work required to create a basic knowledge graph from scratch.
Nevertheless, structured data should not automatically be treated as verified truth. Information may be missing, mappings may be imperfect, and source material may contain errors. Data extracted from Wikipedia can also reflect the limitations of the underlying articles.
For reliable results, users should validate important facts against authoritative sources, document the dataset version, and check licensing conditions before redistributing data or using it commercially.
DBpedia Dataset vs. Wikipedia and Wikidata
DBpedia, Wikipedia, and Wikidata are related, but they serve different purposes.
| Feature | DBpedia | Wikipedia | Wikidata |
|---|---|---|---|
| Primary purpose | Structured knowledge and linked data | Human-readable encyclopedia | Collaborative structured knowledge base |
| Main representation | RDF and knowledge graph relationships | Articles and supporting page structures | Items, properties, and statements |
| Typical access | SPARQL, linked data, downloads | Website and page APIs | Website, APIs, and query services |
| Common use | Semantic applications and research | Reading and researching topics | Structured data retrieval and reuse |
Wikipedia is useful when readers need detailed explanations, context, and references. Wikidata is designed specifically for collaboratively maintained structured facts. DBpedia extracts and organizes information from Wikipedia and related sources into its own knowledge representation.
These resources can complement one another, but they are not interchangeable. Their coverage, update processes, identifiers, and data models differ.
If you are choosing a source for a new project, compare the actual fields and update requirements of each resource rather than assuming one is universally better.
How Beginners Can Start Working With DBpedia
Beginners can explore the DBpedia dataset through a small, manageable project before attempting large-scale data processing.
A practical starting approach is to follow these steps:
- Choose a topic: Select a subject such as cities, films, authors, or technology companies.
- Explore the available data: Visit the official website and identify relevant properties and entity types.
- Test a SPARQL query: Retrieve a limited number of records to understand how relationships work.
- Inspect the results: Check for missing values, duplicate entities, and unexpected classifications.
- Export or download data: Obtain only the records or files needed for your project.
- Build a small application: Use the results to create a search feature, data visualization, or basic knowledge graph.
- Validate important facts: Compare significant results with reliable source material.
You do not need to download the entire dataset to begin learning. A small query can demonstrate how structured information works and help you determine whether DBpedia fits your goals.
As your project grows, consider using an RDF library, a local triple store, or a graph-processing tool to manage larger collections of data. Keep track of the source, version, and retrieval date so that your results can be reproduced later.
Conclusion
The DBpedia dataset is a valuable resource for transforming encyclopedia-derived information into structured knowledge that computers can search, connect, and analyze. Its use of RDF, SPARQL, and linked data makes it relevant to artificial intelligence research, semantic search, knowledge graph development, academic studies, and data integration.
Its greatest strength is the ability to represent relationships between entities across many subject areas. However, users must account for missing information, inconsistent coverage, changing source material, and the limitations of public query services.
For beginners, the best starting point is the official DBpedia website and its SPARQL documentation. By testing small queries, exploring the available datasets, and validating important facts, you can determine how DBpedia can support your particular research or software project.
Frequently Asked Questions (FAQs)
1. What is the DBpedia dataset used for?
The DBpedia dataset is used for semantic search, knowledge graph development, artificial intelligence research, entity linking, academic analysis, and connecting structured information from different sources.
2. Is DBpedia free to use?
DBpedia provides publicly accessible datasets and services. However, licensing requirements can vary depending on the dataset, included content, and release. Check the applicable licensing and attribution requirements before using or redistributing the data.
3. How can I download the DBpedia dataset?
You can find downloadable resources through the DBpedia Databus. Choose the relevant files and formats for your project.
4. What is SPARQL in DBpedia?
SPARQL is a query language used to retrieve information from RDF-based datasets. It lets users search for entities, properties, and relationships in the DBpedia knowledge graph.
5. Is DBpedia the same as Wikipedia?
No. Wikipedia is an encyclopedia designed primarily for human readers. DBpedia extracts and organizes information into structured data for machine processing and linked data applications.
6. Can DBpedia be used for machine learning?
Yes. It can support tasks such as entity linking, knowledge graph construction, and feature generation. Its suitability depends on the quality, coverage, and freshness of the data required by the model.
7. Is the DBpedia dataset updated regularly?
DBpedia publishes updated datasets and maintains services with different update mechanisms. The timing depends on the resource and release process, so consult the Latest Core documentation for current details.
8. What is the difference between DBpedia and Wikidata?
DBpedia primarily extracts and organizes information from Wikipedia and related resources, while Wikidata is a collaboratively maintained structured knowledge base. Both provide machine-readable information, but their data models and maintenance processes differ.